
Konverta Lab · Free tool
Can your audience see your brand or proposition?
Upload a pack, shelf, ad or social post. In seconds, see where eyes go, and how much attention your brand and proposition really get.
Konverta.ai's free attention heatmap shows where your audience is likely to look on a pack, shelf, ad or social post, and how much attention your brand, proposition, claim or price gets. It runs entirely in your browser; your image never leaves your device.
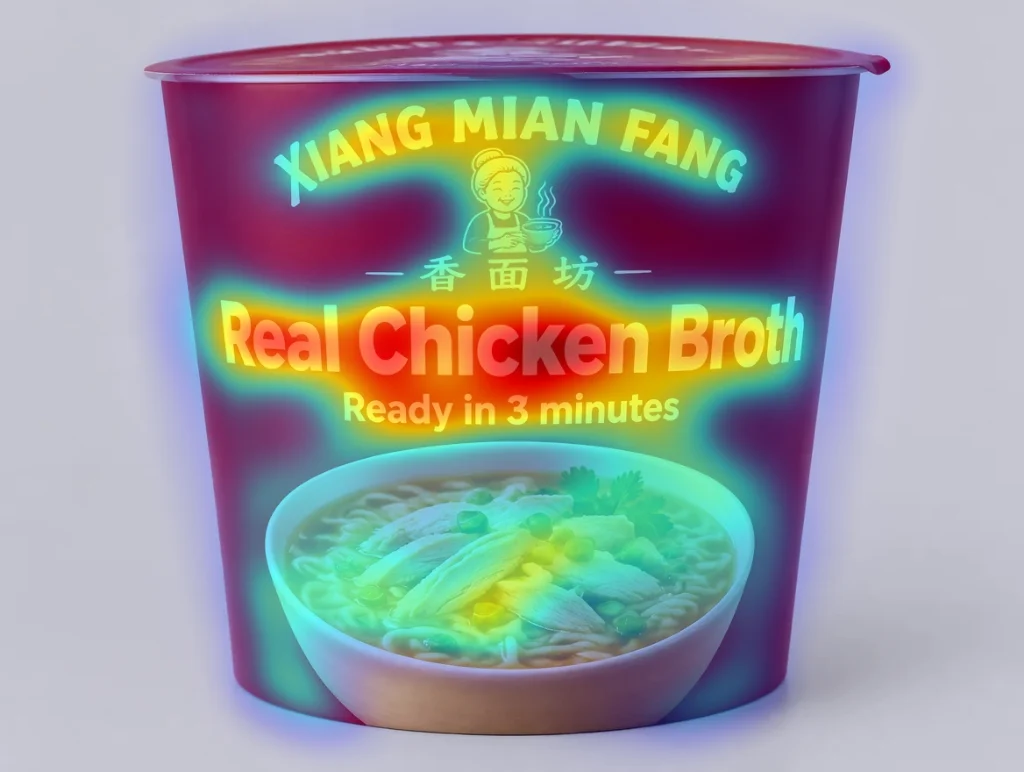


Proposition 2.5% → 31%Product 20% → 27%Brand 27% → 22%


Proposition <0.1% → 41%Product 18% → 39%Brand 2.2% → 10%Clutter 53% → 0%
Fictional brand, same boxes on both versions. Share of predicted attention from the model on this page, not eye-tracking.
Is your brand seen?
Box your logo or name and get its share of attention.
Does your proposition land?
Check the claim, price or call to action isn't in a cold spot.
Which version wins?
Test versions before you print or publish, and keep the strongest.
01 Try it
Try it: your image, your numbers.
- 1 Add an image
- 2 See where eyes go
- 3 Mark your brand and proposition
Loading the example pack...
02 From a real project
46% to the native-script name9% to all Latin-letter text
On a global instant-noodle brand's export pack, our analysis found 46% of predicted attention went to the native-script name and only 9% to Latin-letter text. We can't show that pack; the fictional "before" pack above recreates the pattern, and the "after" shows what changes when the proposition gets the space.
Want this run across your whole range, shelf photos or ad creative?
We build business-critical AI workflows: whole-range audits, shelf-photo analysis and creative pre-checks inside your approval flow.
03 How it works
How it works & FAQ
How the model works & references
Not eye-tracking: a computational saliency model, with citations
No camera, no test participants. The tool runs a computational saliency model: it predicts where eye fixations are likely to land, using published methods that were developed and evaluated against eye-tracking data in the research literature.
- 40%
Spectral residual saliency
Looks at the image's frequency spectrum and keeps what is "unexpected" compared with typical natural images: text, objects and edges that stand out from their surroundings. Hou & Zhang, 2007 [1]
- 30%
Centre-surround contrast
Compares each spot's colour and brightness with its neighbourhood, at two scales. Things that differ from what surrounds them pull the eye. Itti, Koch & Niebur, 1998 [2]
- 20%
Text prior
Gives extra weight to areas with dense letter-like edges (both vertical and horizontal strokes), because text attracts gaze even when people aren't asked to read. Motivated by Cerf, Frady & Koch, 2009 [4]
- 10%
Frequency-tuned saliency
Measures how far each region's colour sits from the image's average colour, which helps whole objects light up rather than just their edges. Achanta et al., 2009 [3]
- ×
Centre bias
People tend to look towards the middle of an image, so the combined map is gently weighted towards the centre (a 35% blend with a centred Gaussian). Tatler, 2007 [5]
From map to percentages
The four maps are mixed with the weights shown, multiplied by the centre bias, softened with a blur of 2% of the image's long edge (roughly the spread of a fixation), rescaled to 0–1, and raised to the power 1.5 so flat backgrounds carry little weight. Share of attention for a box = the sum of the map inside the box ÷ the sum over the whole image. Boxes that don't overlap, plus "everything else", add up to 100%.
Limits
- It is a bottom-up model: it doesn't know brand familiarity, the viewer's task or what they are looking for.
- Faces have no dedicated detector, so faces may be under-weighted.
- It has not been validated in an eye-tracking study of our own.
- Use it to compare versions and spot problems, not as absolute truth.
References
- Hou, X. & Zhang, L. (2007). Saliency Detection: A Spectral Residual Approach. IEEE Conference on Computer Vision and Pattern Recognition (CVPR). doi:10.1109/CVPR.2007.383267
- Itti, L., Koch, C. & Niebur, E. (1998). A Model of Saliency-Based Visual Attention for Rapid Scene Analysis. IEEE Transactions on Pattern Analysis and Machine Intelligence, 20(11), 1254–1259. doi:10.1109/34.730558
- Achanta, R., Hemami, S., Estrada, F. & Süsstrunk, S. (2009). Frequency-tuned Salient Region Detection. IEEE Conference on Computer Vision and Pattern Recognition (CVPR). doi:10.1109/CVPR.2009.5206596
- Cerf, M., Frady, E. P. & Koch, C. (2009). Faces and text attract gaze independent of the task: Experimental data and computer model. Journal of Vision, 9(12):10. doi:10.1167/9.12.10
- Tatler, B. W. (2007). The central fixation bias in scene viewing: Selecting an optimal viewing position independently of motor biases and image feature distributions. Journal of Vision, 7(14):4. doi:10.1167/7.14.4
Is my image uploaded anywhere?
No. The image is decoded, analysed and exported entirely inside your browser, in a background Web Worker on your own device. It is never sent to Konverta.ai or anyone else, and it is gone when you close the tab. Our analytics only record that the tool was used (for example, that an example was opened or a PNG was exported), never the image.
Is this eye-tracking?
No. No camera and no test participants are involved. It is a computational saliency model that predicts where eye fixations are likely to land, built from published methods that were evaluated against eye-tracking data: spectral residual saliency (Hou and Zhang, 2007), centre-surround contrast (Itti, Koch and Niebur, 1998), frequency-tuned saliency (Achanta et al., 2009), a text prior motivated by Cerf, Frady and Koch (2009) and a centre bias (Tatler, 2007).
The share for an area is the predicted attention inside it divided by the predicted attention over the whole image. Full details are under How the model works.
How accurate is a predicted attention heatmap?
It is a prediction, not a measurement: predicted attention from a computational saliency model, not eye-tracking with real people. It does not read words, know your brand or model what your audience is looking for.
Use it to compare versions and spot problems early, then validate big decisions with eye-tracking or audience research.
What is an attention heatmap tool used for?
Pack design reviews, adapting packs for export markets, checking shelf standout, pre-checking ads and social posts before media spend, and testing versions before you print. Marking areas answers one question: how much of the attention goes to your brand, proposition, claim or price, compared with everything else.
Can Konverta.ai run this on a whole range, shelf photos or ad creative?
Yes. Konverta.ai builds business-critical AI workflows, for example batch attention analysis across a full product range, shelf audits from store photos, or creative pre-checks wired into your approval process. Message Kenneth on WhatsApp at +65 8785 5691 or email hello@konverta.ai.